Paper Summary: Efficient Pre-Training with Token Superposition
Copied verbatim from my Twitter thread (22 June 2026).
"Efficient Pre-Training with Token Superposition"
This paper finds that we can group up tokens to create a much more efficient training regime, achieving 2-4x speedups for the same loss.
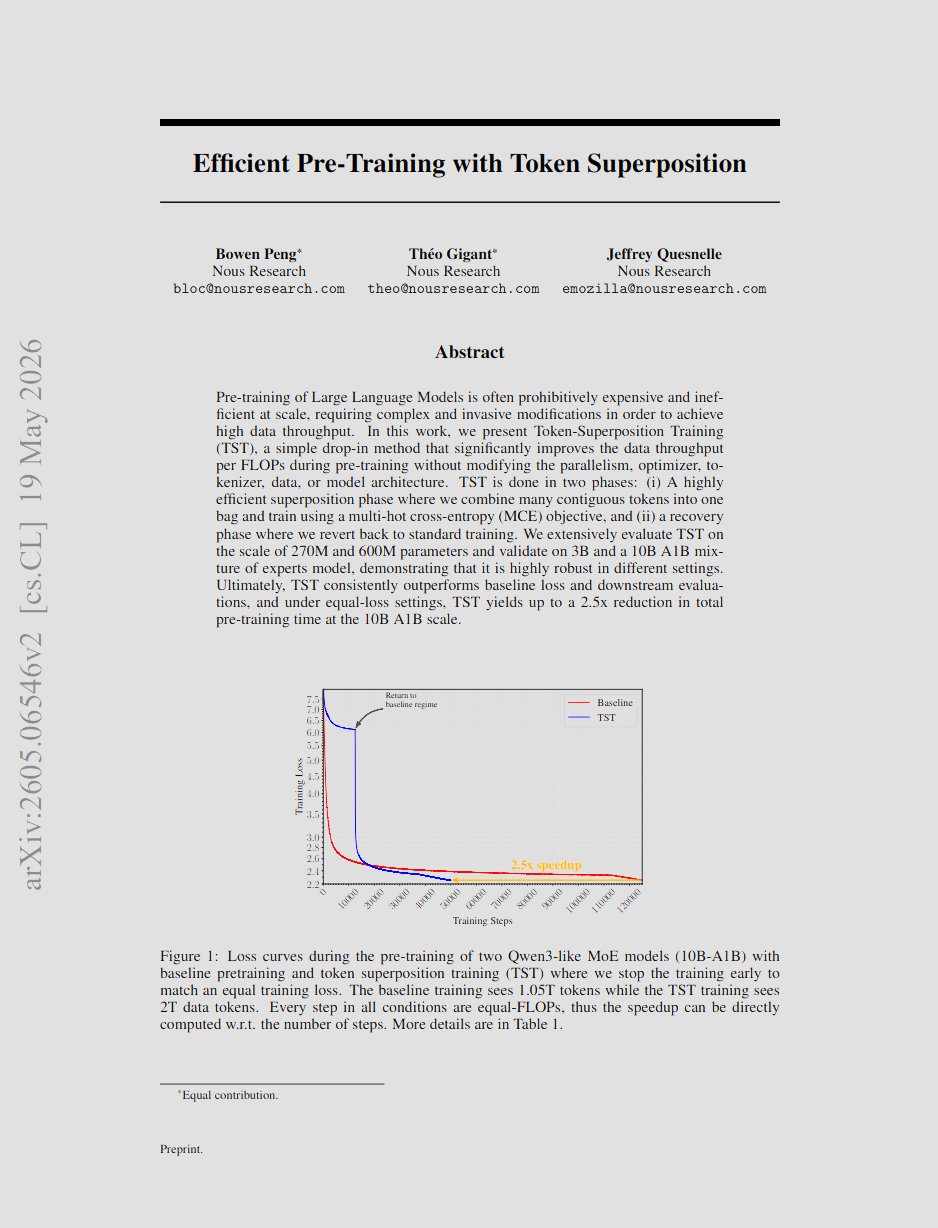
Paper can be found here: https://arxiv.org/abs/2605.06546
Great blog post to pair with it, interactive diagrams: https://nousresearch.com/token-superposition
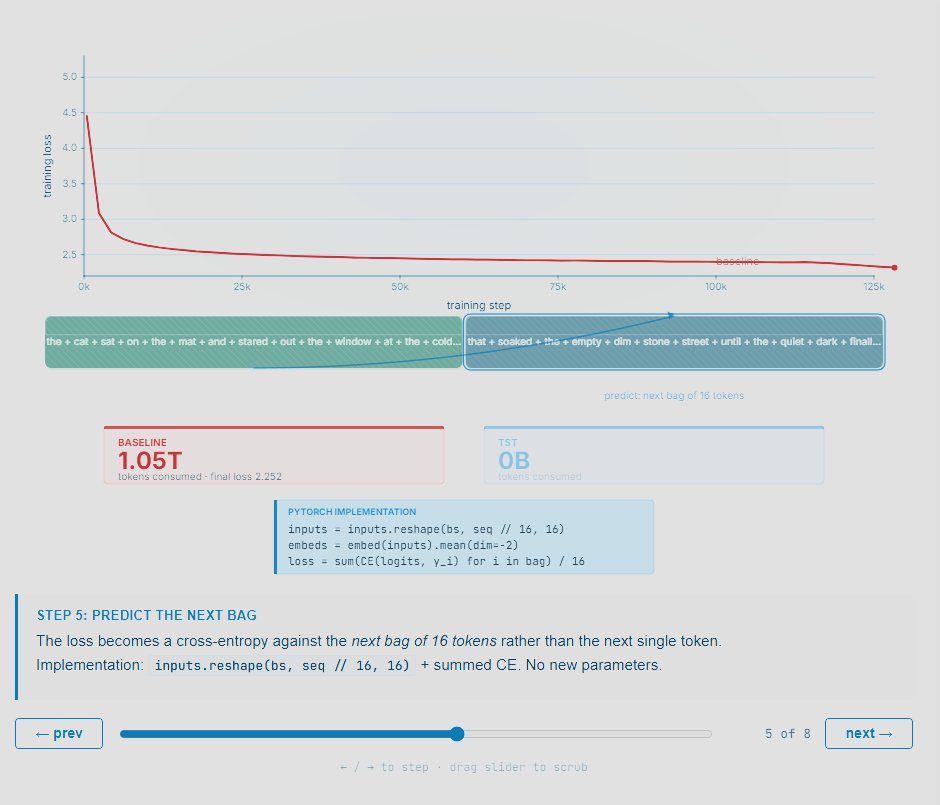
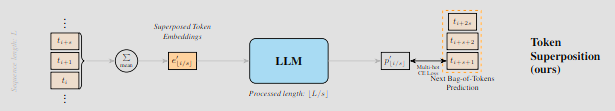
The paper groups up tokens into bags of size s, and predicts the next bag.
They call this Superposition (great naming).
Given its own intuitive CE loss.
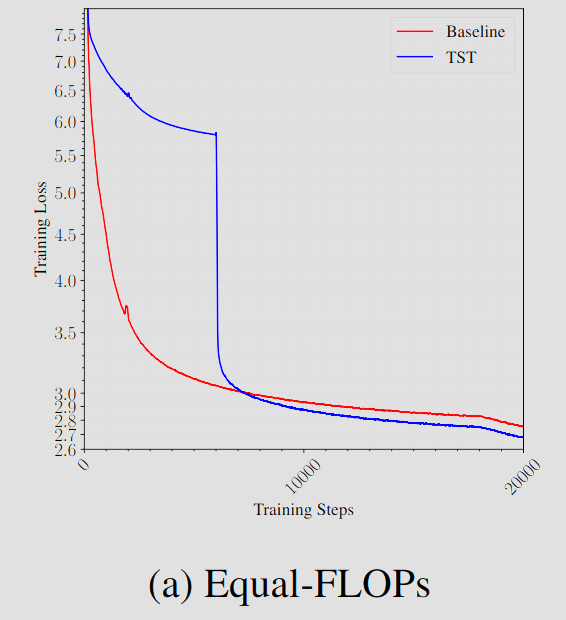
For the first 30% of training we follow this method of next-token-bag prediction.
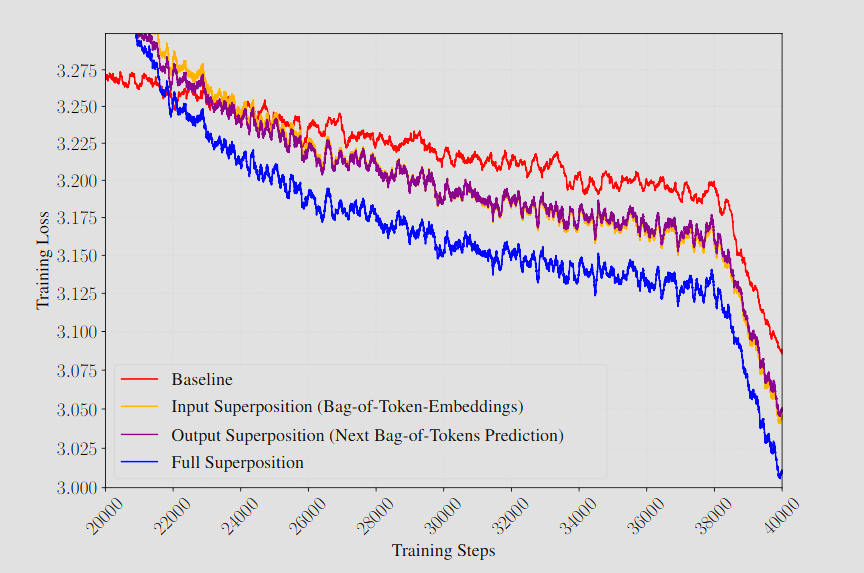
Then, they switch to normal token prediction! Brave! But look at that loss curve fall!
This is necessary because the bags of tokens are unordered.
I'm really a fan of how well-written this paper is. It's easy to follow, with great diagrams and very clear results.
Full details of GPUs, GPU-hours, hyperparameters sweeps, even code in the appendix (!) allows reproduction.
All too many papers miss this! But we need it for science!
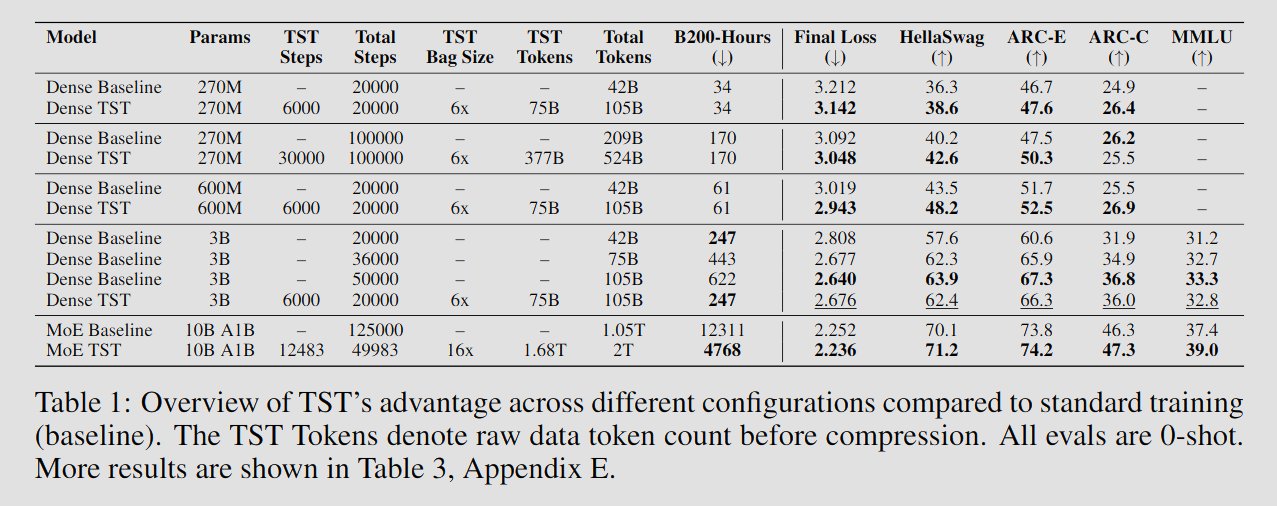
(This was especially refreshing after reading the GRAM paper which was terrible in these aspects)
And we finally have this really interesting breakdown, discussion and ablation study of all the moving parts in this paper.
Really fantastic stuff.
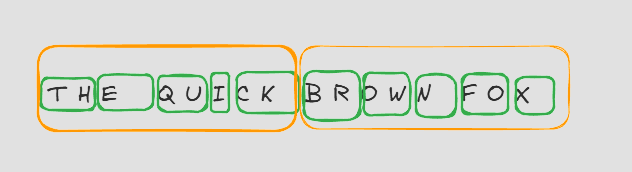
Riffing on my own here, you can start to see a general, hierarchical method reveal itself.
First - we had BPE on top of bytes to make tokens.
Now bags of tokens help performance.
Hierarchy seems to help.
I wonder how it pairs with token diffusion?
(Shitty diagram for visual.)
Overall big fan of this from @NousResearch.
Great communication and rigorous research. Will be reading more papers + following more closely.
Well done!