Paper Summary: Recirculation and Full Bandwidth Transformer
Copied verbatim from my Twitter thread (20 August 2026).
What's the difference between Recirculation and Full Bandwidth Transformer?
They are very similar!
The similarities: Both:
- feed back a deep latent from previous token to the next
- can be trained with expensive sequential prefill stage
Now the differences:
1. Recirculation can be performed *without any training at all*
However it performs better with training, or 'adaptation'.
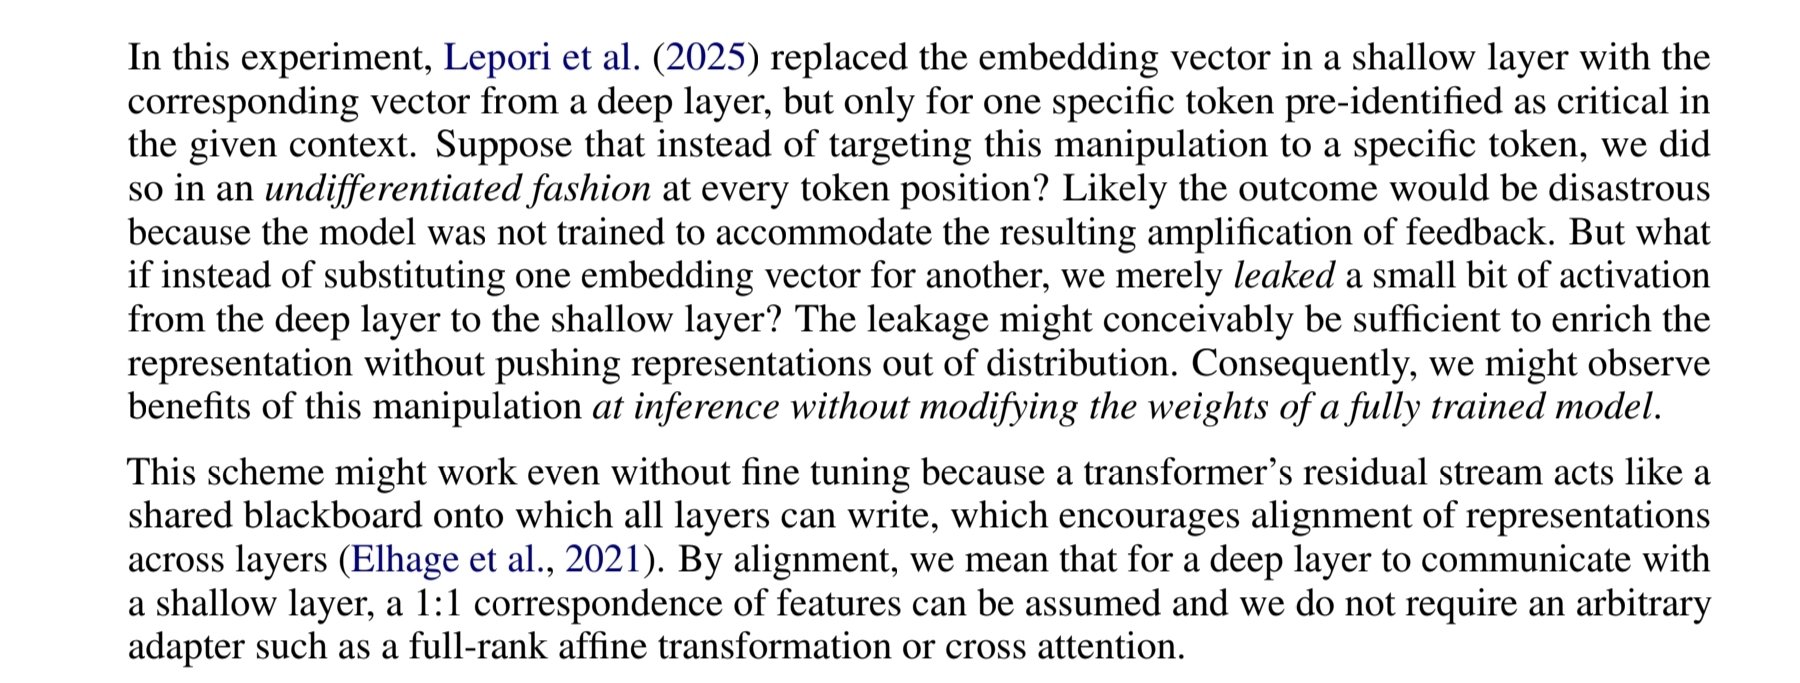
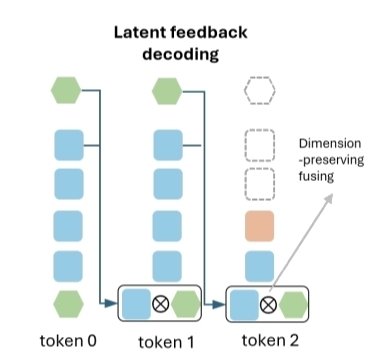
2. Recirculation studies the latent space passing from layer N on token T --> layer M < N on token T+1.
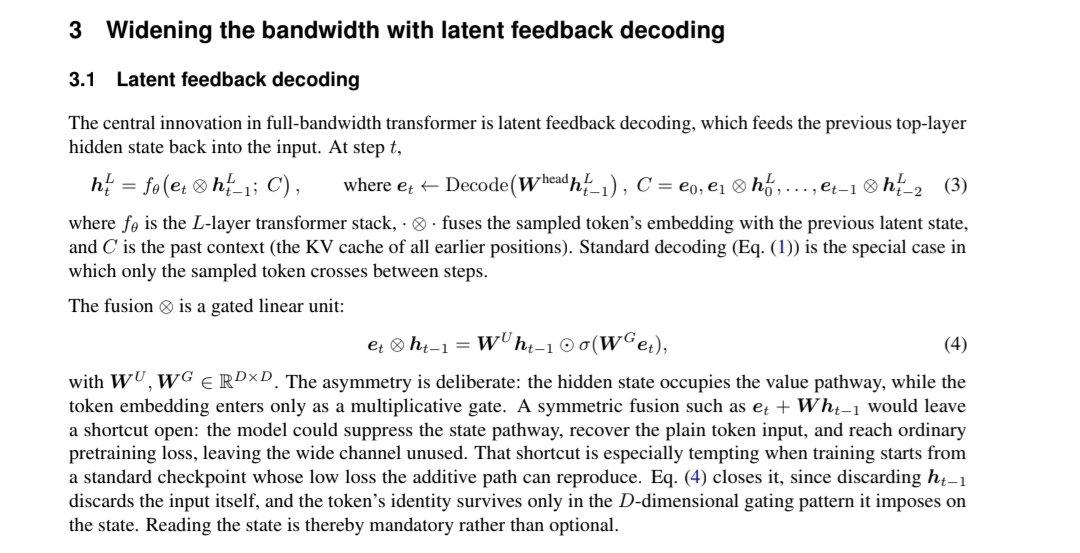
Full-Bandwidth focusses on final layer passed in to next token
(Left: Recirc, Right: Full-Bandwidth)
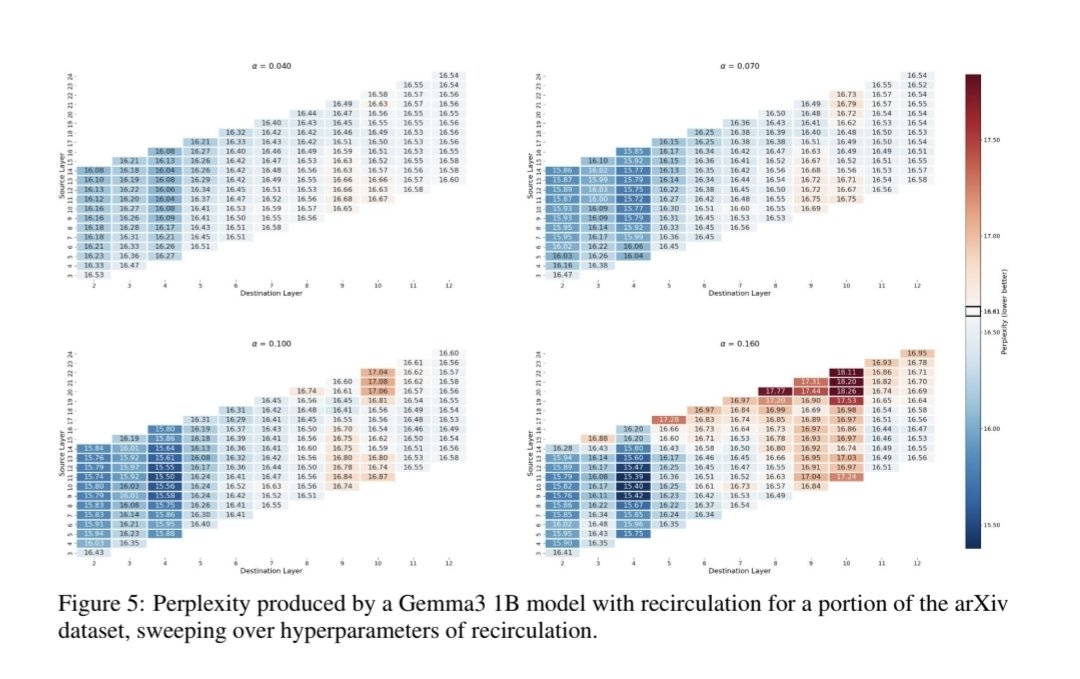
3. For training, Recirculation prefill training was thought expensive.
Full Bandwidth Transformers found the latent space is trained quickly and cheaply via a 2- and 3-stage partial prefill.
Obviously we need to try combining these!
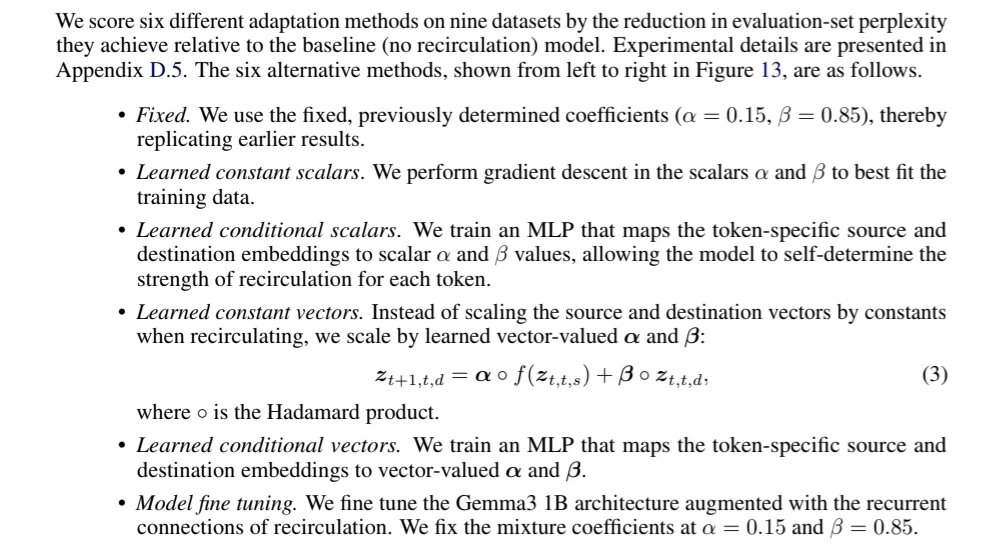
4. Full Bandwidth Transformer is opinionated about the layer combinations, providing a single function with a strong performance.
Recirculation studies flexible family of combinations, introducing new hyperparameters.
(Left: Recirculation, Right: Full Bandwidth)
It's always interesting when two separate authors land upon the same key idea at the same time!
Both add key insights that will multiply the other's effectiveness. This is exciting!!
Full Bandwidth Transformer:
https://arxiv.org/abs/2608.08888
Recirculation:
https://arxiv.org/abs/2608.17981
Apologies as I may have missed some things - I am on holiday!
Please feel free to fill in gaps and correct me!